What mattered · week 45
Expert analysts mostly followed a hidden lean Anthropic gave Claude; all 15 AI models tested found more errors than human peer reviewers did; Gemini 4 Carbon and GPT-6.1 Terra make near-frontier AI cheaper; and inside one company 10% of staff produce 90% of the AI gain.
This week's two studies belong together: AI now finds more errors than expert reviewers did, and is also good at steering what experts decide.
What mattered
When Claude leaned one way, expert analysts mostly followed. Anthropic gave Claude Code a secret coin-flip lean on each choice in a data analysis. The 50 expert analysts using it went with that lean 86% of the time; 50% would mean no influence. The lean was deliberately strong, but in real use Claude's defaults are the lean. I think this is a big deal.
| Analysts given a secret AI lean | Share |
|---|---|
| Went with the agent's lean | 86% |
| Repeated its arguments as their own | 77% |
| Credited the agent | 15% |
Anthropic randomised trial, 50 professional analysts, Claude Code (Opus 4.8). The first row counts choices; the others count analysts.
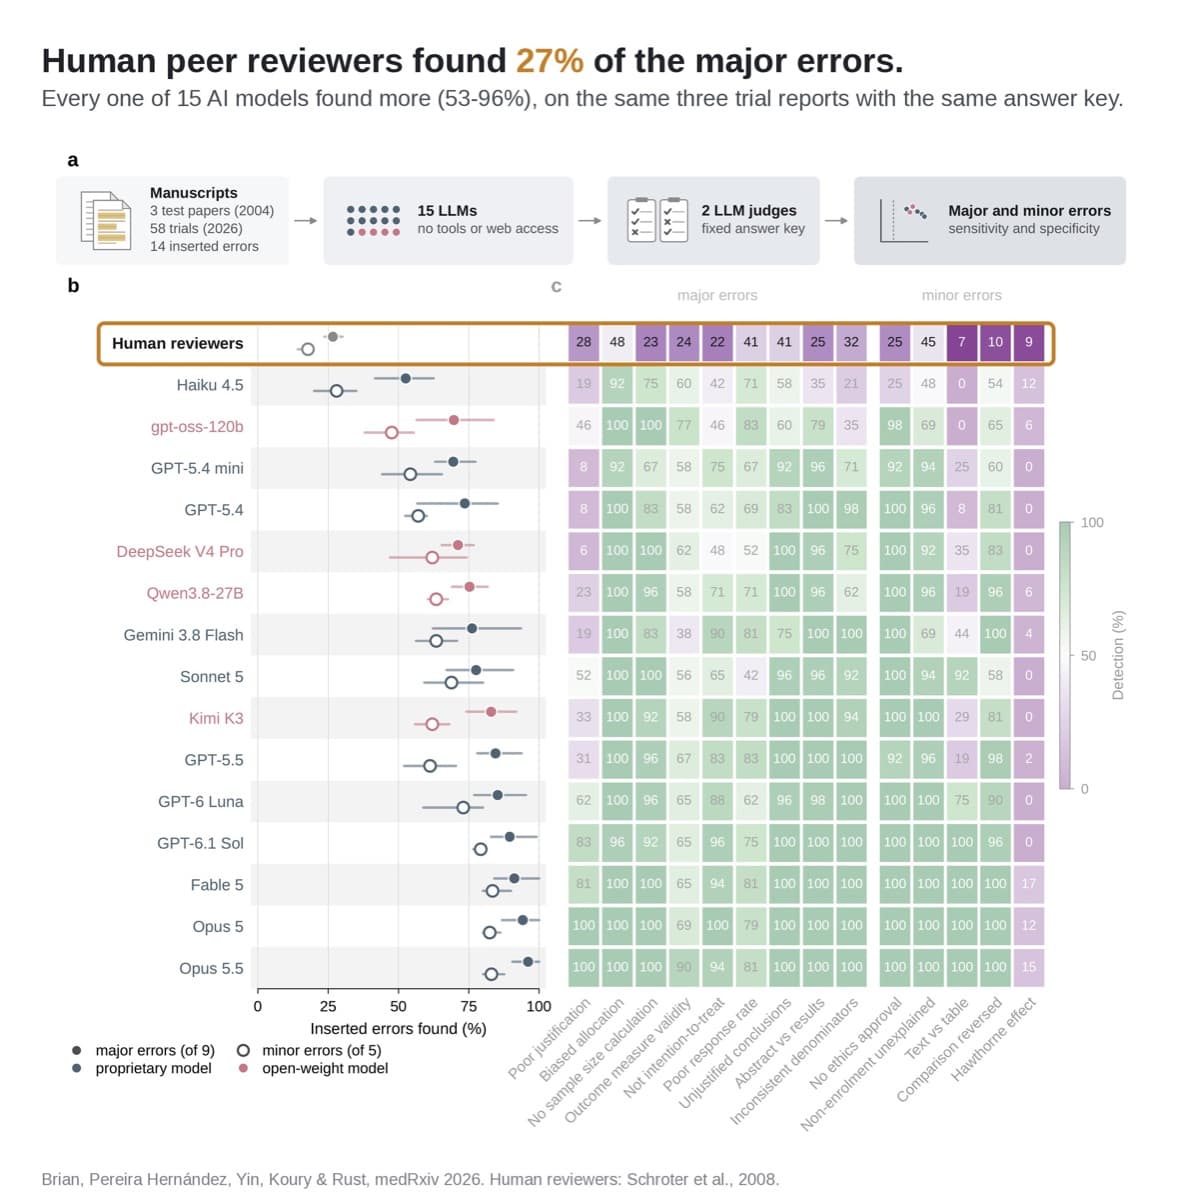
All 15 AI models tested found more errors than human peer reviewers. On the same three trial reports, reviewers in 2008 caught 27% of the planted major errors; the models caught 53% to 96%. AI judges did the scoring, and most of the authors work on AI-assisted review. Read more
Google and OpenAI priced near-frontier AI well below Opus 5.5. On one cost-per-task leaderboard, Gemini 4 Carbon came second to Opus 5.5 at $1.76 a task against $7.13; for now it is limited to cyber defenders. OpenAI says GPT-6.1 Terra is about nine times cheaper per task than Opus 5.5 at max effort. Read more on Carbon and Terra.
One thing to try
Write tasks an agent can pick up without you. A ready task says what done looks like, names the files or area, says what's been ruled out, and fits in one session.
First step: before your next hand-off, ask the AI "Rewrite this task so someone with no context could finish it: what done looks like, where to work, what's ruled out." Five minutes. From my essay on agent control planes
The bigger picture
A head of AI at a huge company told Alex Lieberman that 10% of staff produce 90% of the AI gain. They say training hasn't changed that. One anecdote, but to me it's skill-biased technical change on steroids, and it matches what I've seen. Read more
From the log
- Claude Code Agent Teams: a lead Claude Code session runs teammates that share a task list; experimental.
What did I miss? Just reply to this email. The rest of what I log is at wayintoai.com/logs.